built on bend-ml.
what I built
I built llama.bend on top of bend-ml to run Llama-architecture language models in Bend. One package runs SmolLM2-135M, SmolLM2-360M and SmolLM2-1.7B on the CPU; only the configuration changes.
The package is published on BendHub as bend-ml-llama. Each weight matrix gets its shape from the model configuration, and the key/value cache carries both its capacity and the number of positions already written.
a concrete example
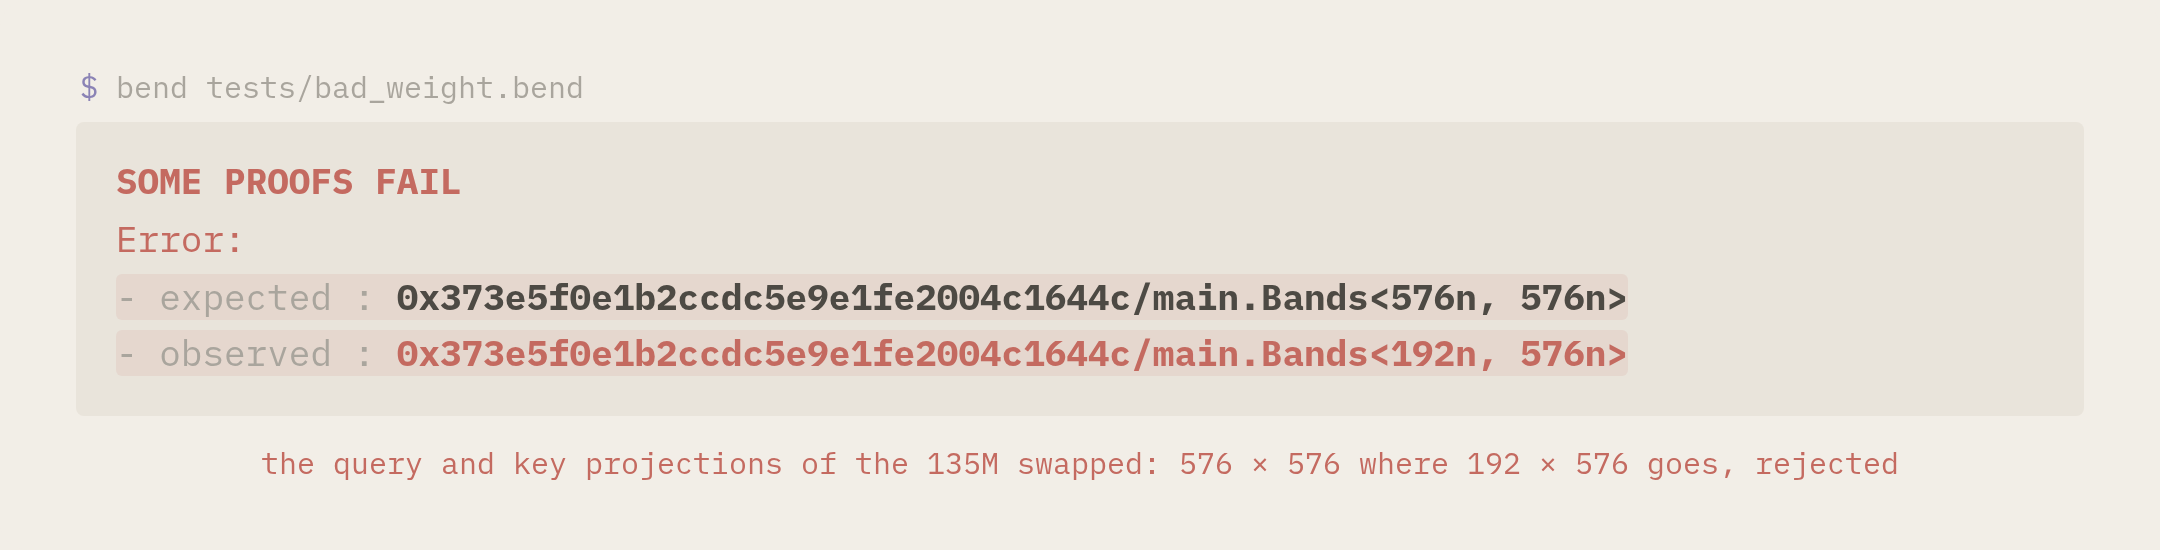
In SmolLM2-135M, the query projection is 576 × 576 and the key projection is 192 × 576. Swapping them is a mistake that the types reject before the model runs.
an error caught by the types
576 × 576192 × 576SOME PROOFS FAIL
expected  Bands<576n, 576n>
observed  Bands<192n, 576n>
The query and key shapes from SmolLM2-135M. Swapping the weights is rejected; the original checker output is linked below.
public source ↗open full image ↗
the decisions
- Derive the weight shapes from one configuration, so the same typed layers serve all three model sizes.
- Check structural laws for query-to-key/value head mapping, causal cache reads, cache capacity, RoPE head splitting, and checkpoint layout.
- Write the tokenizer in Bend too, and compare it independently with the reference tokenizer. Proofs are erased during compilation.
the results
- For each of the three models, 32 greedy tokens and the decoded text match transformers on 12 tested prompts, using transformers 5.19 in F32 with eager attention.
- Separate checks compare logits on 11 prompts and the highest-scoring token at 88 positions. Matching generated tokens does not mean every floating-point value is identical.
- The tokenizer matches reference ids on 68 fixed texts and 600 random texts; decoding is compared on 1,500 random token sequences.
the limits
- CPU only, base models and greedy decoding, with no chat template. The vectors between layers are lists whose lengths are not carried in their types.
- In the published 2026-10-13 comparison, SmolLM2-1.7B is 3.7–4.9 times slower than llama.cpp. Loading is the slowest part. BENCHMARK.md records the hardware, versions and measurements; these are not predictions for other machines.
- The laws establish structural guarantees. Numerical accuracy and generated text are tested against references, not formally proved.
reference README ↗ · published comparisons ↗